Apodex 1.1: Agentic Intelligence for Complex Research
> Apodex 1.1 turns AI reasoning into long-running research workflows with files, code, Agent Teams, verification, recovery, and open Mini models for developers.
🎧 Listen — ~9 min
Ready · Apodex 1.1: Agentic Intelligence
Apodex 1.1 is presented as a reasoning-first model and online workbench for complex, long-horizon research. The release is aimed at a gap that ordinary deep-search products often leave open: finding and summarizing information is useful, but research work usually continues through files, data cleaning, code execution, analysis, review, and revision before a conclusion is ready for scrutiny.
Released on August 24, 2026, Apodex 1.1 is designed to move reasoning into that execution loop. The system can work with papers, datasets, spreadsheets, images, code, and file environments while maintaining task state across a longer workflow. Its product direction combines a hosted workbench with an open local ecosystem built around the Apodex 1.1 Mini checkpoints and the FrontierAgent runtime.
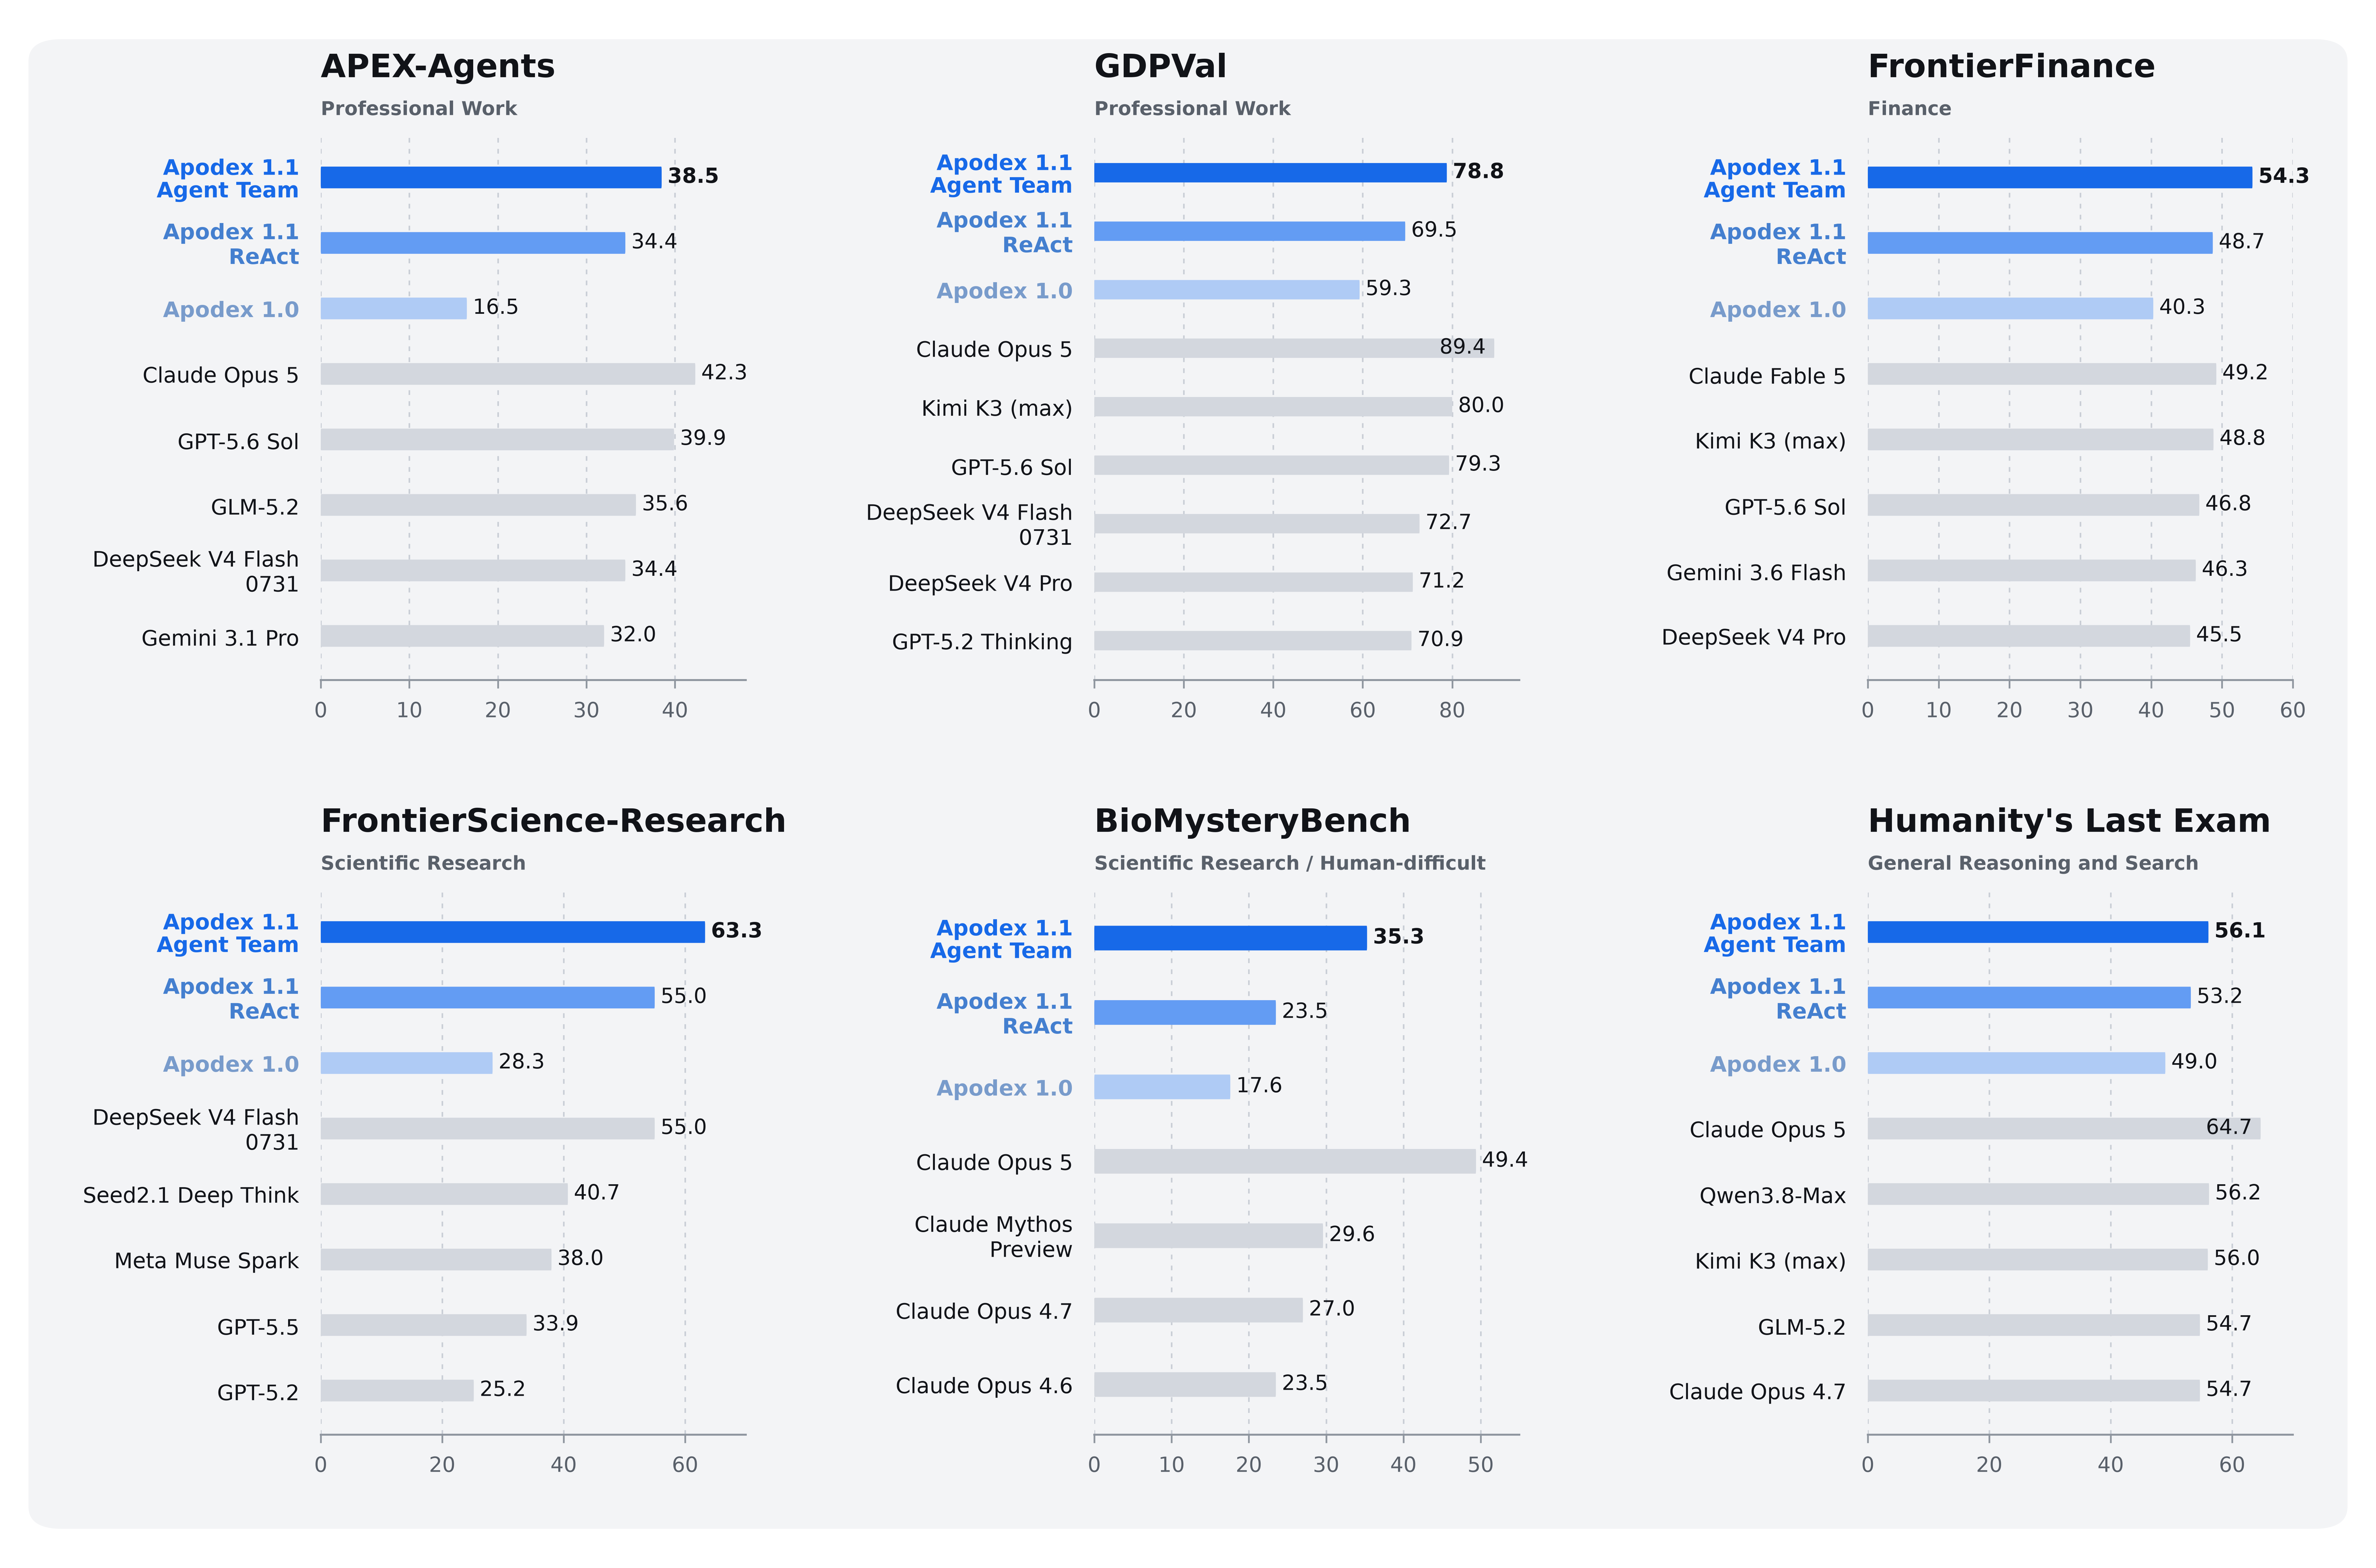
Official Apodex 1.1 benchmark visual from the ApodexAI FrontierAgent repository. The scores are vendor-reported and should not be treated as independently reproduced results.
What Apodex 1.1 changes
The central claim in Apodex’s release announcement is that a correct answer and a completed, verifiable piece of work are different capabilities. A conventional assistant may produce a polished report from retrieved text. A complex research workflow may instead require the system to inspect raw files, choose a method, write and run code, interpret intermediate results, recover from an error, and trace the final statement back to evidence and artifacts.
Apodex 1.1 is built around that second workflow. Search, file processing, code execution, and tool calling are treated as part of reasoning rather than as disconnected add-ons. The model can use those tools to test a premise, inspect a dataset, check an assumption, or revise a plan when the evidence changes.
The release describes six capabilities as the foundation of a complete long-running task:
- Understanding the actual goal and constraints.
- Acting inside real file, code, and tool environments.
- Maintaining and updating state across many dependent steps.
- Incorporating new feedback during execution.
- Recovering from failure without restarting the entire task.
- Producing a deliverable that can withstand review.
That positioning makes Apodex 1.1 less like a search box and more like a research execution layer. It also raises a higher standard: the important question is not only whether the final prose sounds convincing, but whether the work can be inspected and reproduced from its inputs, operations, and evidence.
From report generation to an online workbench
Apodex’s official example is a survival-analysis task involving EASIX and overall survival after EBV reactivation in patients receiving allogeneic transplantation. A useful system for this kind of work must read tables and data dictionaries, inspect missing values, select an appropriate statistical method, run analysis code, generate Kaplan–Meier curves and statistical tables, and explain how it handled problems in the data.
The same pattern appears in materials science, bioinformatics, and computational drug design. Powder X-ray diffraction data, molecular docking inputs, and nanoindentation measurements are not simply web pages waiting to be summarized. They are specialized artifacts that need to be opened, transformed, analyzed, and checked.
Apodex 1.1’s workbench model is designed around this chain:
Original editorial diagram based on the official Apodex 1.1 release description. It illustrates the workflow concept, not an internal implementation claim.
The key product implication is continuity. If a researcher adds a file or changes a requirement midway through a task, Apodex says the system should preserve valid intermediate work, update the plan, and continue from the current state rather than discarding the entire run.
Asynchronous Agent Team coordination
Apodex 1.1 also introduces asynchronous Agent Team behavior in its Deep Discover mode. The official description says the model can decide whether a task should be broken down, how many subagents to use, and when to consolidate or redirect their work.
That is different from a fixed workflow in which every branch is predetermined. One agent may inspect literature, another may analyze a dataset, and another may check methods or search for counterexamples. As useful findings arrive, the main task can absorb them without waiting for every branch to finish. Slow or failed branches do not necessarily block the remaining work.
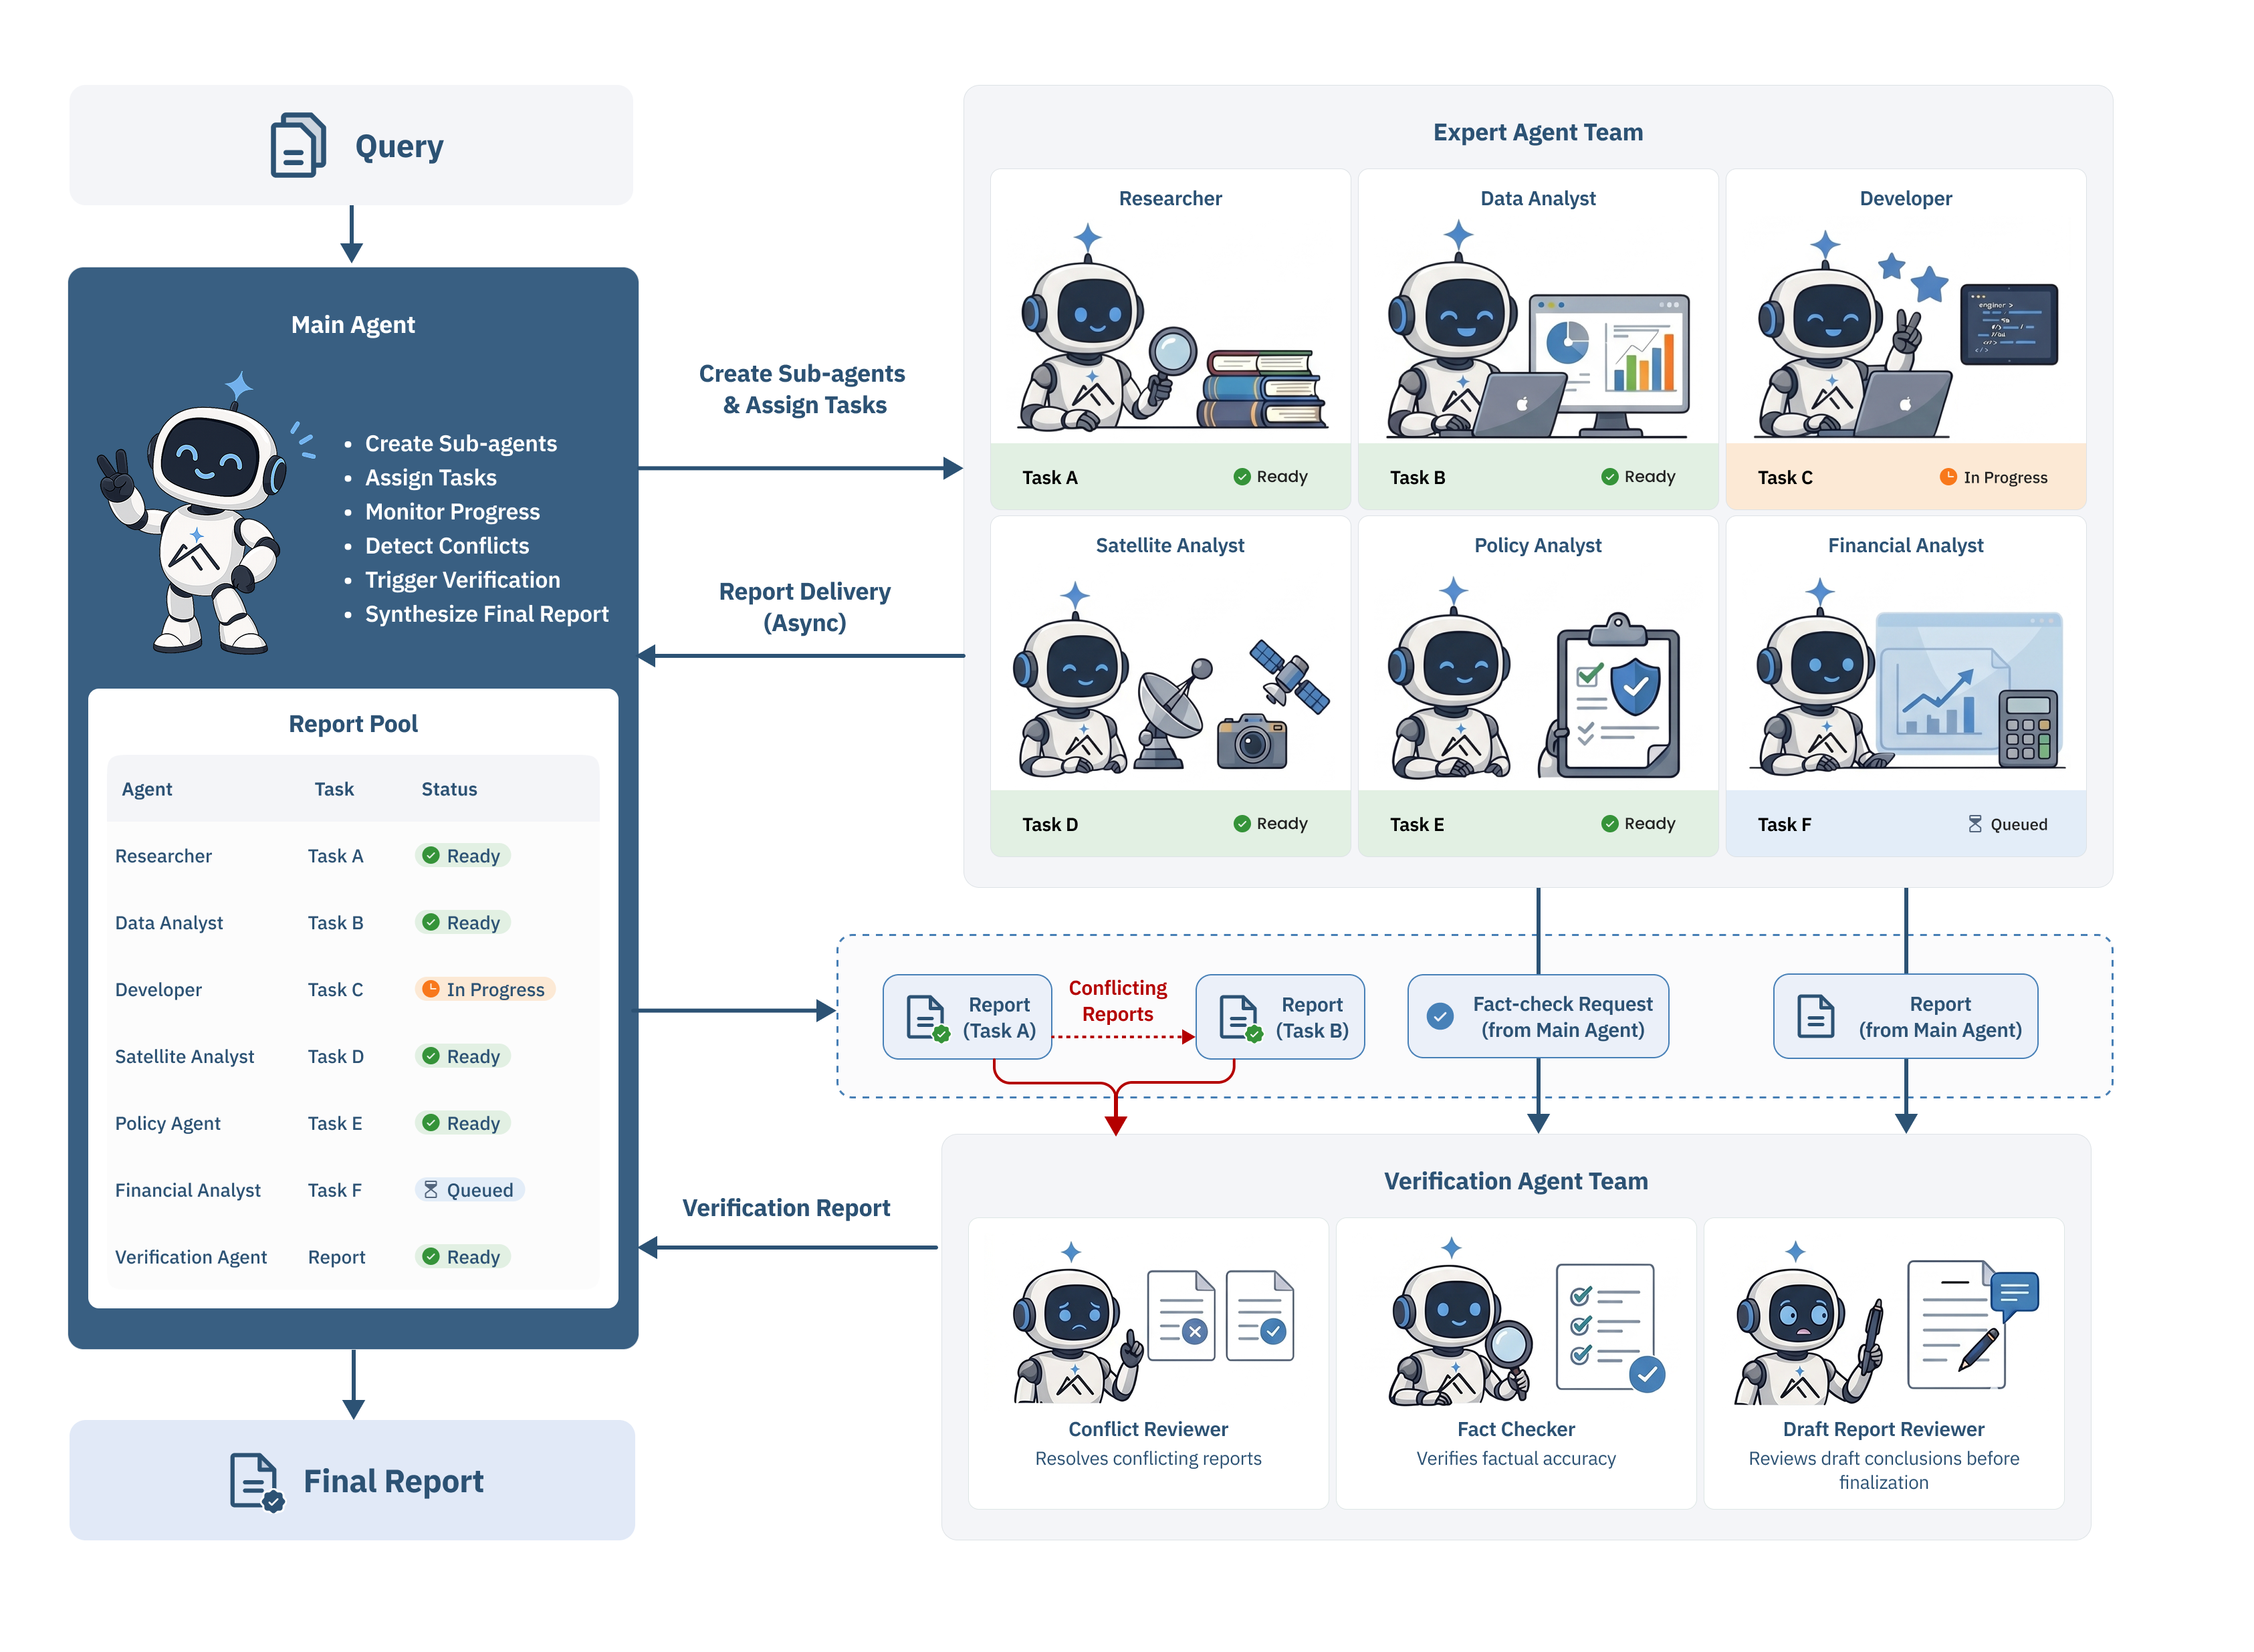
Official Agent Team architecture visual from the ApodexAI FrontierAgent repository. Used as a reference image with attribution to the project.
The practical benefit is not parallelism alone. It is the feedback loop between the coordinator, subagents, tools, and user. A long research task can be re-prioritized while it is running, and the user can add context, ask for a deeper check, pause a path, or redirect the system.
FrontierAgent’s open-source implementation makes this design more concrete. Its repository describes two native workflows:
- ReAct: one stateful agent reads files, researches, runs commands, writes deliverables, and iterates in a task-scoped sandbox.
- Agent Team: a coordinator maintains a task board, delegates bounded assignments to parallel subagents, collects structured reports, and synthesizes the result.
The runtime also includes checkpoints, traces, approvals, recovery, and an evaluation layer. Mutating operations can show a diff and require approval, while session artifacts preserve the run’s checkpoint, logs, and trajectories.
Open models, open harness, and an important distinction
Apodex is opening part of the Apodex 1.1 ecosystem, not necessarily every component of the hosted product. The official blog presents the full Apodex 1.1 model as the complete capability envelope, while Apodex 1.1 Mini plus FrontierAgent is the path for local and open deployment.
The official Hugging Face collection lists several Mini variants:
| Variant | Official listing | Practical role |
|---|---|---|
| Apodex-1.1-mini | 36B | Base released Mini checkpoint |
| Apodex-1.1-mini-FP8 | 36B | FP8 deployment variant |
| Apodex-1.1-mini-NVFP4 | 19B | NVIDIA FP4 quantized variant |
| Apodex-1.1-mini-GPTQ-Int4 | 7B | GPTQ Int4 quantized variant |
Apodex’s release post calls Mini a 35B model, while the current Hugging Face listings show 36B for the base and FP8 variants. The safest description is therefore “approximately 35B/36B,” with the discrepancy noted rather than silently choosing one number.
The model cards and FrontierAgent repository identify Apache 2.0 licensing for the released open components. FrontierAgent is designed to connect to an OpenAI-compatible model endpoint and documents local serving paths using tools such as SGLang or vLLM. That makes the harness reusable, but local deployment still depends on suitable hardware, model-serving configuration, and the operational cost of running long agent tasks.
There is no verified official listing in the reviewed sources for full Apodex 1.1 weights. Developers should not assume that the hosted full model is open-weight merely because the Mini checkpoints and harness are available.
Benchmark claims and how to read them
The official model documentation reports results for Apodex 1.1 Agent Team including 38.5 on APEX-Agents, 78.8 on GDPVal, 54.3 on FrontierFinance, 63.3 on FrontierScience-Research, 35.3 on BioMysteryBench, and 56.1 on Humanity’s Last Exam. The Mini results include 50.2 on FrontierFinance and 27.7 on APEX-Agent.
Apodex says Agent Team consistently outperforms its ReAct setup and reports leading compared-system scores on FrontierFinance and FrontierScience-Research. These numbers are useful as release evidence, but they remain vendor-reported claims. The published material does not independently establish that all systems used identical prompts, tool budgets, model access, evaluator conditions, or contamination controls.
For engineering decisions, benchmark charts should be treated as a starting point. A team evaluating Apodex should run its own representative tasks, record tool calls and artifacts, measure recovery behavior, and compare total latency and cost—not only final-answer accuracy.
Availability and pricing
Apodex is available as an online service through apodex.ai, with a separate platform/API surface at platform.apodex.ai. The official pricing page describes a usage-credit model. Credit consumption is calculated dynamically from model-token consumption and tool invocation costs, so the final cost depends on the complexity of the request, the model usage, and the number of tools called.
The pricing page reviewed for this article did not expose a stable per-token price table. Teams should confirm current rates and subscription terms before building a production budget around a fixed cost assumption. Deep Discover is described by Apodex as a preview available through its Frontier Program.
What developers should evaluate first
Apodex 1.1 is most interesting when the task has all of the following characteristics:
- Multiple files or specialized data formats.
- Several dependent analysis steps.
- A need for code execution or structured artifacts.
- New evidence or requirements arriving during the run.
- A meaningful cost when the answer is wrong.
- A need to preserve traces and explain how the conclusion was reached.
A sensible pilot should begin with a non-production dataset and a clearly bounded deliverable. Measure whether the system can identify bad inputs, recover from failed commands, preserve intermediate files, cite the evidence behind important statements, and ask for approval before consequential mutations.
For the local path, start with the official FrontierAgent documentation, use a restricted task-scoped workspace, and keep external credentials separate from research inputs. Do not allow a long-running agent to inherit broad production permissions simply because it can execute code or use shell tools.
FAQ
Is Apodex 1.1 an AI search engine?
Not exactly. Search is one of its tools, but Apodex positions 1.1 as a reasoning-first workbench for long-horizon research involving files, code, data, task state, verification, and revision.
Can I run Apodex 1.1 locally?
The released Apodex 1.1 Mini checkpoints can be used with the open FrontierAgent ecosystem and an OpenAI-compatible serving endpoint. Hardware and serving requirements vary by checkpoint and quantization format.
Is the full Apodex 1.1 model open source?
The reviewed official sources clearly document open Mini checkpoints and the Apache 2.0 FrontierAgent runtime. They do not establish that the hosted full model weights are publicly available.
Are the benchmark scores independently verified?
Not by the sources reviewed here. They are official Apodex or model-card claims and should be validated with task-specific testing before being used as a procurement or deployment decision.
How does Apodex charge users?
The official pricing page describes usage-based credits calculated from model-token consumption and tool invocation costs. Current concrete rates should be checked directly before planning spend.
Conclusion
Apodex 1.1 is a notable attempt to make agentic intelligence useful beyond the final report. Its focus is the complete execution loop: understand the goal, work inside real environments, maintain state, coordinate parallel investigations, recover from failure, accept user intervention, and subject key claims to review.
The release is especially relevant to research and engineering teams whose work is too file-heavy, iterative, or high-stakes for a single search-and-summarize prompt. The open Mini checkpoints and FrontierAgent runtime give developers a path to experiment locally, while the hosted workbench targets heavier workflows.
The right way to assess the system is not to ask whether it sounds intelligent in a demo. Run it on representative tasks, inspect the artifacts and traces, test failure recovery, verify the citations, and measure cost. That is the standard Apodex 1.1 is setting for itself.
Sources and visual credits
- Apodex 1.1: Scaling Agentic Intelligence for Complex Work — official release announcement.
- Apodex official product site — product tiers and positioning.
- Apodex 1.1 Hugging Face collection — released model variants.
- Apodex-1.1-mini model card — model documentation and reported evaluations.
- ApodexAI/FrontierAgent — open runtime, Agent Team workflow, evaluation suite, and assets.
- Apodex pricing — usage-credit pricing description.
- Apodex Discovery arXiv paper — related heavy-duty solver and reality-benchmark research.
Visual credits: the benchmark chart and Agent Team image are official project assets downloaded from the ApodexAI/FrontierAgent repository and reproduced with source links. The Mermaid workflow diagram is original editorial artwork based on the official release description.
Related reading
Continue exploring related AI engineering and developer tooling topics:
Keep reading
Related reading
⚡ Daily AI Model Drop — Get Kimi K3 benchmarks before Twitter
Join 2,400+ AI engineers. 1 email/day, no spam, unsubscribe anytime