Muse Glimmer: Meta’s 30B Local Agent Deep Dive
> Muse Glimmer is Meta’s 30B Apache 2.0 open-weight local AI agent model. This guide covers hardware, quantization, tool use, multimodal input, local vs cloud trade-offs, setup decisions, and safety.
🎧 Listen — ~10 min
Ready · Muse Glimmer: Meta’s 30B Local A
Meta released Muse Glimmer on August 10, 2026 as an open-weight model aimed at a problem developers keep running into: capable agents are usually cloud-dependent, while local models often trade away long-horizon execution, multimodal input, and reliable tool use. Muse Glimmer tries to close that gap with a 30-billion-parameter model designed for always-on agent workflows on consumer hardware.
Quick answer: Muse Glimmer is Meta’s 30B Apache 2.0 open-weight multimodal agent model for local coding, function calling, visual input, and offline automation. Its practical advantage is privacy and device control; its main constraint is the memory and engineering required to run a quantized model reliably.
Muse Glimmer is designed for local, multimodal agent workflows: coding, vision, tool use, and offline execution on capable consumer hardware.
The release is notable for two reasons. First, Meta is publishing the weights under the permissive Apache 2.0 license. Second, the model is not positioned as a general-purpose chatbot alone. Meta describes it as an agentic model for local coding, function calling, evaluation, personal automation, and offline workflows. That makes the practical question less about leaderboard placement and more about whether a developer can run a useful, private agent without renting a cloud GPU.
Muse Glimmer at a glance
| Question | Direct answer |
|---|---|
| What is it? | Meta’s 30B Apache 2.0 open-weight multimodal model for local agents. |
| What can it do? | Local coding, function calling, image understanding, multi-step planning, and failure recovery. |
| What hardware is the target? | A Mac or PC with a single consumer GPU; Meta says the approximately 4-bit model is under 20 GB before runtime overhead. |
| Why does it matter? | Sensitive context can stay on-device, and agents can continue working without a network connection. |
| What is the main caveat? | A local model still needs a sandbox, tool allowlists, retry limits, and human approval gates. |
What Meta is actually releasing
Muse Glimmer is a 30B multimodal model from Meta Superintelligence Labs. Meta says it is available through Hugging Face, with developer documentation for building local agents. The official Meta announcement is the primary source for the release date, license, hardware target, and deployment guidance. Integrations for llama.cpp, MLX, and ExecuTorch are planned for the days following launch, while Ollama, LM Studio, Unsloth, vLLM, SGLang, Together AI, Fireworks AI, and OpenRouter are listed as deployment or ecosystem partners.
The license matters. Apache 2.0 is familiar to commercial engineering teams and permits modification, redistribution, and integration subject to the license terms. It does not remove the need to review Meta’s model documentation, acceptable-use requirements, and the operational risks of running model-generated code. “Open weights” is also more precise than casually calling every released model fully open source: the weights may be available while some training data, infrastructure, or evaluation details remain proprietary.
Meta says Muse Glimmer was assessed under its Advanced AI Scaling Framework before release. That is useful release context, but it is not a substitute for independent testing. Teams should reproduce the workloads that matter to them: tool-call accuracy, prompt-injection resistance, latency, memory use, coding success, and recovery from failed actions.
Why 30B is an interesting local target
At full precision, a 30-billion-parameter model would require more than 55 GB of memory, according to Meta. That is outside the comfortable range of most consumer GPUs. The release therefore leans heavily on quantization. Meta says its approximately 4-bit version can fit in under 20 GB, leaving room for the KV cache, image encoder, and speculative-decoding drafter inside a 24 GB or 32 GB memory envelope.
That memory target is strategically important. A 7B or 14B model can be easy to run, but may struggle with extended plans or complex tool schemas. A much larger model can be more capable but becomes impractical for a laptop. A quantized 30B model sits between those extremes: demanding enough to require a serious local machine, but potentially accessible to a Mac with a large unified-memory configuration or a desktop GPU such as an RTX 5090.
The engineering trade-off is straightforward. Quantization reduces memory pressure and can improve throughput, but developers should measure quality on their own prompts rather than assuming that a vendor’s reported “minimal to no degradation” applies to every task. Long contexts, image-heavy inputs, large tool definitions, and concurrent sessions can all increase memory use beyond the headline model size.
Speculative decoding is more than a benchmark trick
Muse Glimmer also ships with a lightweight drafter based on DFlash. Instead of asking the main model to generate one token at a time, the drafter proposes blocks of tokens. The main model verifies those proposals in parallel and corrects rejected tokens. Meta says this can produce identical output quality while making generation significantly faster. That is a vendor claim, so treat it as a starting point rather than an independent benchmark result.
For ordinary chat, that is a latency improvement. For agents, it is more consequential: slow generation compounds across planning, tool calls, and follow-up actions. A faster local model can make the difference between an interactive agent and one users abandon.
There is a systems caveat: speculative decoding adds another model and therefore another memory and integration concern. Teams should benchmark complete workflows, not just tokens per second. The meaningful measurement is time to successful task completion, including tool execution and retries.
The agent capabilities Meta emphasizes
Meta’s release highlights seven capabilities that are usually difficult to combine in a compact local model.
- End-to-end task completion across DeepSearch QA, MCP-Atlas, τ-Bench, and SWE-Bench-style workloads.
- Reliable function calling with precise schemas over extended workflows.
- Multi-step reasoning that maintains a plan across several actions.
- Failure recovery when a tool returns an error or unexpected data.
- Interleaved text and image input through a dedicated perception encoder.
- Compatibility with OpenClaw and other agent orchestration patterns.
- Controllable reasoning effort, allowing developers to trade speed for quality.
The failure-recovery claim deserves special attention. Tool errors are normal in production: an API times out, a file moves, a permission changes, or a browser page returns a different structure. An agent that stops at the first error is a demo. An agent that diagnoses, retries safely, and asks for approval when the action is risky is closer to a usable product.
Still, recovery should be bounded. A local model must not be allowed to loop indefinitely or repeat destructive actions. Put timeouts, retry budgets, idempotency keys, filesystem boundaries, and approval gates around the model. Local execution improves privacy and availability; it does not automatically make autonomous behavior safe.
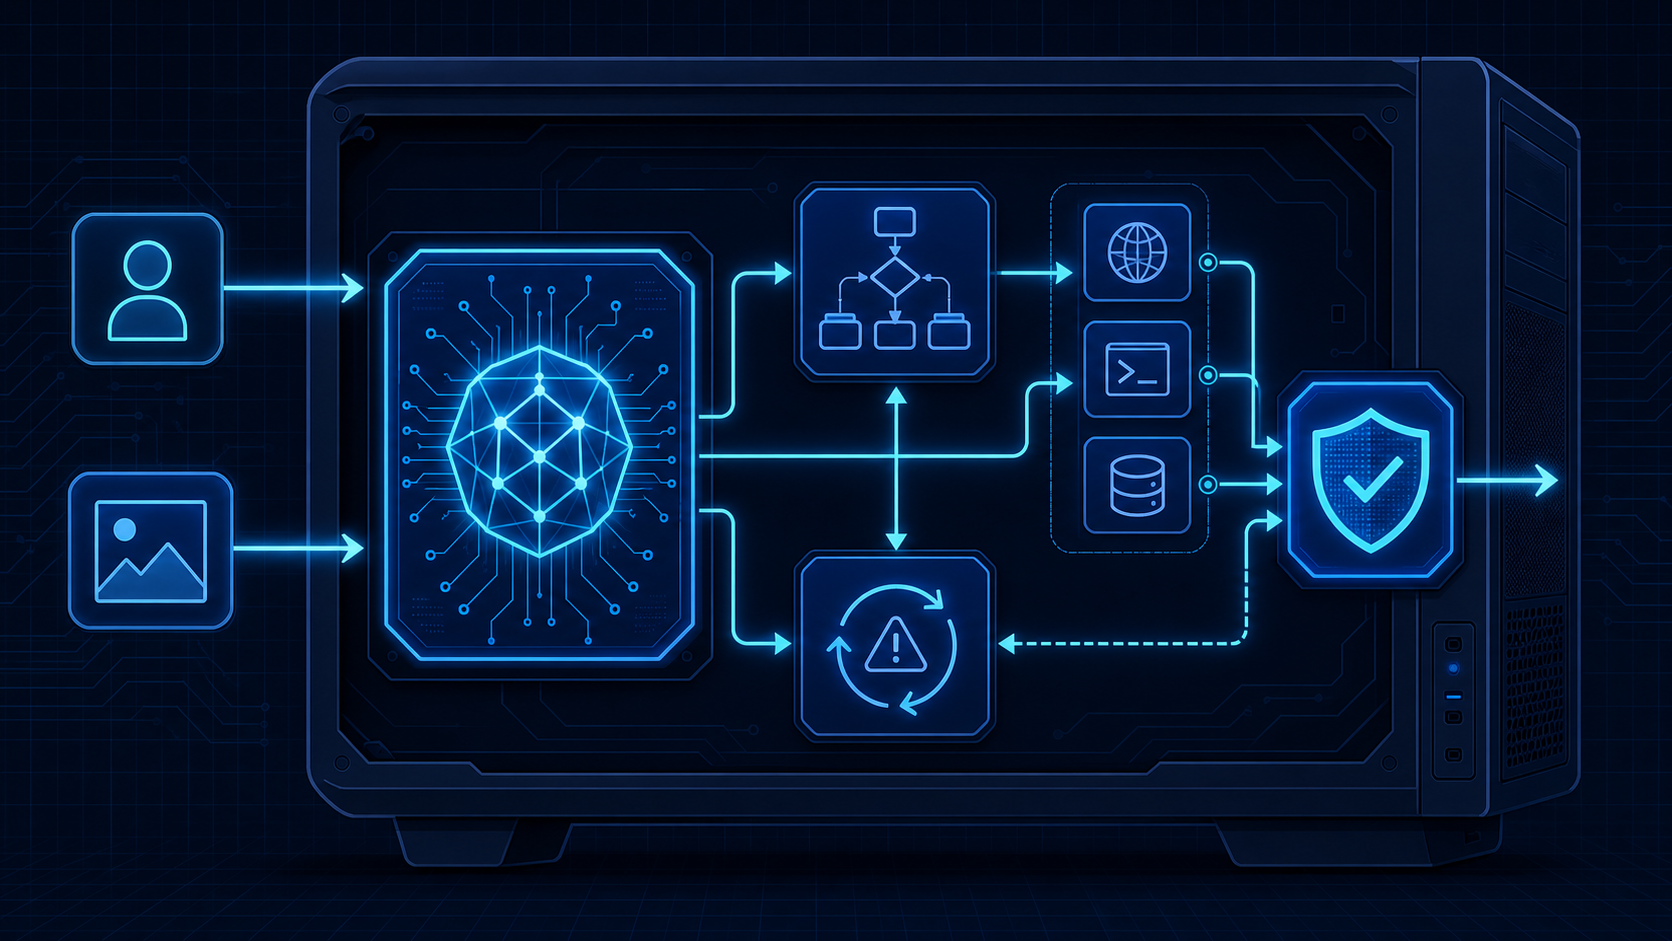
The safest local-agent design keeps model capabilities behind explicit tools, bounded retries, and human approval for risky actions.
A practical local-agent architecture
A sensible first experiment is a narrow coding or research scaffold rather than an unrestricted personal assistant. Run the quantized model behind an OpenAI-compatible or framework-native server, then expose a small allowlisted tool set:
- Read-only repository search.
- A test runner with a fixed working directory.
- A patch tool that writes only inside a disposable worktree.
- Structured notes or task state.
- Human approval before network access, deployment, deletion, or credential use.
This design lets developers test the model’s core strengths—planning, tool selection, multimodal inspection, and recovery—without giving it broad control over a workstation. For coding, compare it against a cloud model and measure successful patches, test-pass rate, review time, tokens generated, and total wall-clock time. For private research, measure citation completeness and whether the model distinguishes retrieved evidence from guesses.
Muse Glimmer’s compatibility list also suggests a portable deployment path. A developer might prototype with LM Studio or Ollama, optimize a Mac deployment through MLX, use llama.cpp for a lightweight local runtime, and move high-throughput serving to vLLM or SGLang. Keeping the scaffold’s tool contracts independent from the inference backend reduces lock-in.
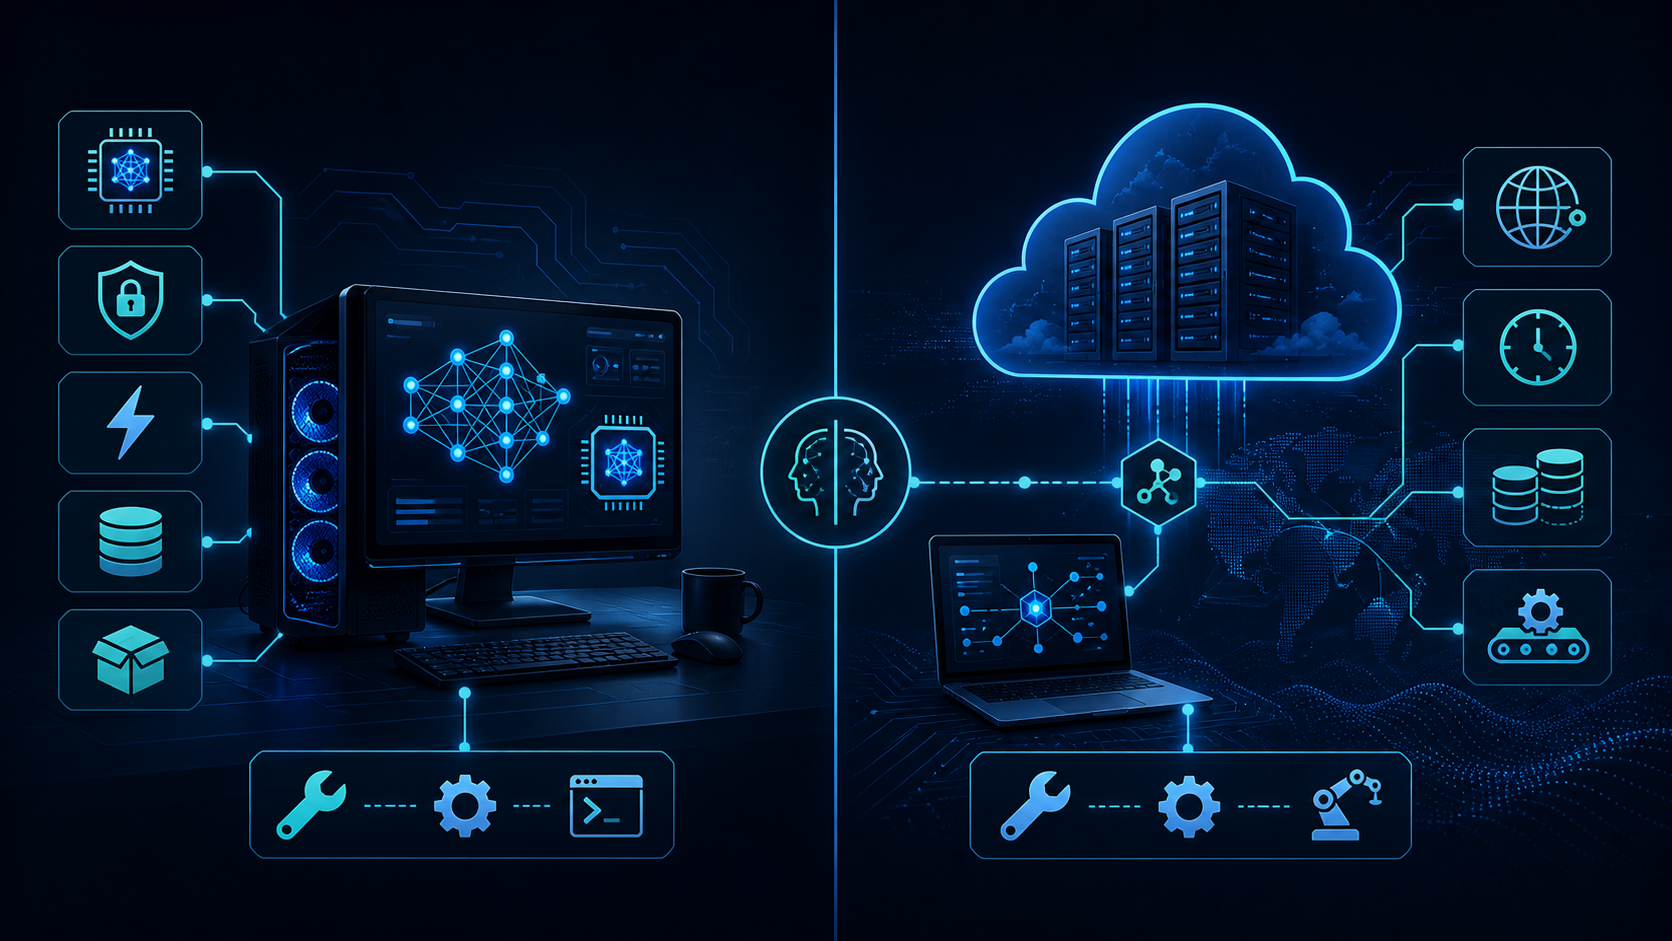
Muse Glimmer vs. a cloud-first agent
| Dimension | Muse Glimmer locally | Cloud-first agent |
|---|---|---|
| Data locality | Sensitive prompts and files can remain on-device | Requests typically leave the device |
| Availability | Can continue during network outages | Depends on network and provider uptime |
| Setup | Requires capable hardware, runtime, and model serving | Fastest path to first use |
| Scaling | Bounded by local memory and thermals | Provider handles fleet capacity |
| Control | Custom tools, permissions, and runtime policies | Managed platform controls |
| Best fit | Private coding, research, and always-on workflows | Teams prioritizing convenience and elastic capacity |
Which should you choose: local or cloud?
Choose Muse Glimmer locally when privacy, offline availability, predictable data locality, and custom tool permissions matter more than turnkey scaling. Choose a cloud-first agent when you need the fastest setup, elastic capacity, or a managed runtime. For most teams, the best evaluation is a side-by-side bake-off on one real workflow—not a leaderboard-only comparison.
How it fits the current agent ecosystem
The release arrives as the ecosystem is splitting into complementary layers. GitHub has made the open-weight Kimi K3 generally available in Copilot, hosted by Fireworks AI, with gradual rollout across VS Code, Visual Studio, Copilot CLI, cloud agent, mobile, JetBrains, Xcode, and Eclipse. Kimi K3 is cloud-hosted inside that product, while Muse Glimmer targets local execution. The comparison is not simply “which model is smarter?” It is cloud convenience and managed integration versus device control, offline availability, and data locality.
Open-source orchestration projects are also moving beyond single-agent wrappers. AgentTeams describes a Manager-Workers architecture with Matrix rooms, human visibility, multiple runtimes, shared storage, and centralized gateway controls. Prime Agent, another active GitHub project, combines a recursive language model loop with a continual harness for durable memories, skills, subagents, and long-running sessions. These projects show where a local model can become useful: not as an isolated executable, but as one component in a controlled runtime.
The model supplies reasoning and tool-use ability, but the surrounding scaffold determines permissions, observability, state, and recovery policy. A strong model in a weak harness is still a risky agent.
Related reading on local agents
If you are evaluating the surrounding stack, compare this model with CodeGraph for local coding-agent context, Qwen-MM-Plugins for multimodal workflows, and Hermes Agent as an open-source agent workbench. These are complementary layers: model, perception/tooling, code context, and runtime orchestration.
The bottom line for developers
Muse Glimmer is one of the more consequential local-agent releases of 2026 because it targets the capability gap between tiny edge models and cloud-first frontier systems. The combination of 30B scale, Apache 2.0 weights, multimodal input, tool use, quantization, and speculative decoding makes it worth testing on capable consumer hardware.
Do not treat the announcement as proof that every laptop can run a frontier replacement. The practical requirements remain substantial, integrations are rolling out, and independent evaluation is still necessary. But the direction is clear: local agents are becoming less about a small chatbot in a terminal and more about private, multimodal systems that can plan, act, recover, and stay available without a network connection.
For an engineering team, the best next step is a controlled bake-off. Pick one real workflow, use a disposable environment, compare Muse Glimmer with a cloud baseline, and record quality, latency, memory, recovery behavior, and review effort. If the local model is good enough, the payoff is not only lower inference cost. It is a different deployment model—one where sensitive context can remain on the device and an agent can keep working when the internet cannot.
Sources and verification
- Meta AI Research: Introducing Muse Glimmer — release claims, license, local hardware target, capabilities, quantization, speculative decoding, and deployment partners.
- Hugging Face: Muse-Glimmer-30B model card — model files, runtime metadata, and published evaluation entries.
- AgentTeams on GitHub and Prime Agent on GitHub — examples of the orchestration layer around an agent model.
Benchmark figures and performance statements above are attributed to Meta or the Hugging Face model card where applicable; they should be independently reproduced before production decisions.
Frequently asked questions
What is Muse Glimmer?
Muse Glimmer is Meta’s 30B open-weight multimodal agent model, built for local reasoning, tool use, coding, visual input, and offline workflows.
Can Muse Glimmer run on a consumer computer?
A quantized build may fit within an approximately 20 GB memory target, but the runtime also needs room for the KV cache, multimodal encoder, operating system, and tools. A 24 GB or 32 GB GPU or a high-memory unified-memory Mac is a more realistic starting point than an ordinary laptop.
Is Muse Glimmer fully open source?
It is more precise to call it an Apache 2.0 open-weight model. The weights are available under a permissive license, but training data, infrastructure, and some evaluation details may remain proprietary.
Is a local agent automatically safer?
No. Local execution improves privacy and can reduce external exposure, but the model still needs sandboxing, allowlisted tools, retry limits, approval gates, and protection against prompt injection and destructive actions.
How should developers evaluate Muse Glimmer?
Use one real workflow and compare it with a cloud baseline on task success, tool-call accuracy, latency, memory use, recovery from errors, citation quality, and human review time.
Keep reading
Related reading
⚡ Daily AI Model Drop — Get Kimi K3 benchmarks before Twitter
Join 2,400+ AI engineers. 1 email/day, no spam, unsubscribe anytime